Collection
Custom sourcing · synthetic generation · human-authored data
Datasets are commissioned and built not bought. A vetted global network of domain contributors, paired with synthetic generation that has cleared methodology review.
Frontier models are only as good as the human data and evaluations behind them. We gather, check and score that data from start to finish, working with vetted AI trainers in every major field. Then we benchmark models on the suites frontier teams actually measure against, including SWE-bench, MLE-bench and Terminal-Bench.
01
Demonstrations, preference pairs and reasoning traces written by people who actually do the work, not crowdsourced guesswork. Everything is collected under a documented method and is ready for SFT, RLHF and agentic training.
Explore the human data pipeline02
Every sample is checked more than once by vetted AI trainers in software engineering, maths, science, medicine, law and finance. Each review is scored against a clear rubric, audited, and easy to reproduce.
See the validation workflow03
We build, run and extend the agentic and professional benchmarks that frontier labs test against. That covers the tasks, the environments, the graders and the human baselines that show where a model really stands.
View the benchmark suiteTrusted methodology
Our domain experts build custom evaluation sets and RLHF pipelines tailored to your models.
Five stages, one operating contract. Each is engage able independently but the gain comes from the loop.
Read the full services briefCustom sourcing · synthetic generation · human-authored data
Datasets are commissioned and built not bought. A vetted global network of domain contributors, paired with synthetic generation that has cleared methodology review.
Text · image · video · audio — multi-layer review
Annotation is treated as a measurement problem. Multi-stage review, inter-annotator agreement floors, and a closed feedback loop into source-stage rubrics.
Benchmarks · rubrics · adversarial probes
Datasets are commissioned and built not bought. A vetted global network of domain contributors, paired with synthetic generation that has cleared methodology review.
Published methodology · agent rubrics · synthetic data
Applied research informs every stage upstream. Papers, technical reports, and methodology notes written by the same teams operating the pipelines they describe.
Custom solutions · platform builds · enterprise scale
Bespoke AI, software, and platform builds from prototype to enterprise scale, with operations bundled. Outcomes contracted, not deliverables.
Anisa and Allvia ship the same evaluation, retrieval, and agent orchestration core as products your team uses daily.
Product 01 — Anisa
Anisa.
The AI onboarding specialist.
Anisa welcomes, trains, and ramps every new hire with the care of a senior people partner at every desk, in every timezone. Day-one provisioning, role-specific learning paths, an always-on AI coach, milestone tracking, and readiness analytics on one surface.
Welcome
Day-one journeys · access · paperwork
Training
AI-led, rubric-scored, recorded
AI coach
24/7 Q&A grounded in internal docs
Readiness
Milestones · ramp velocity · signals
Readiness signal
On track. Ship-ready ahead of schedule.

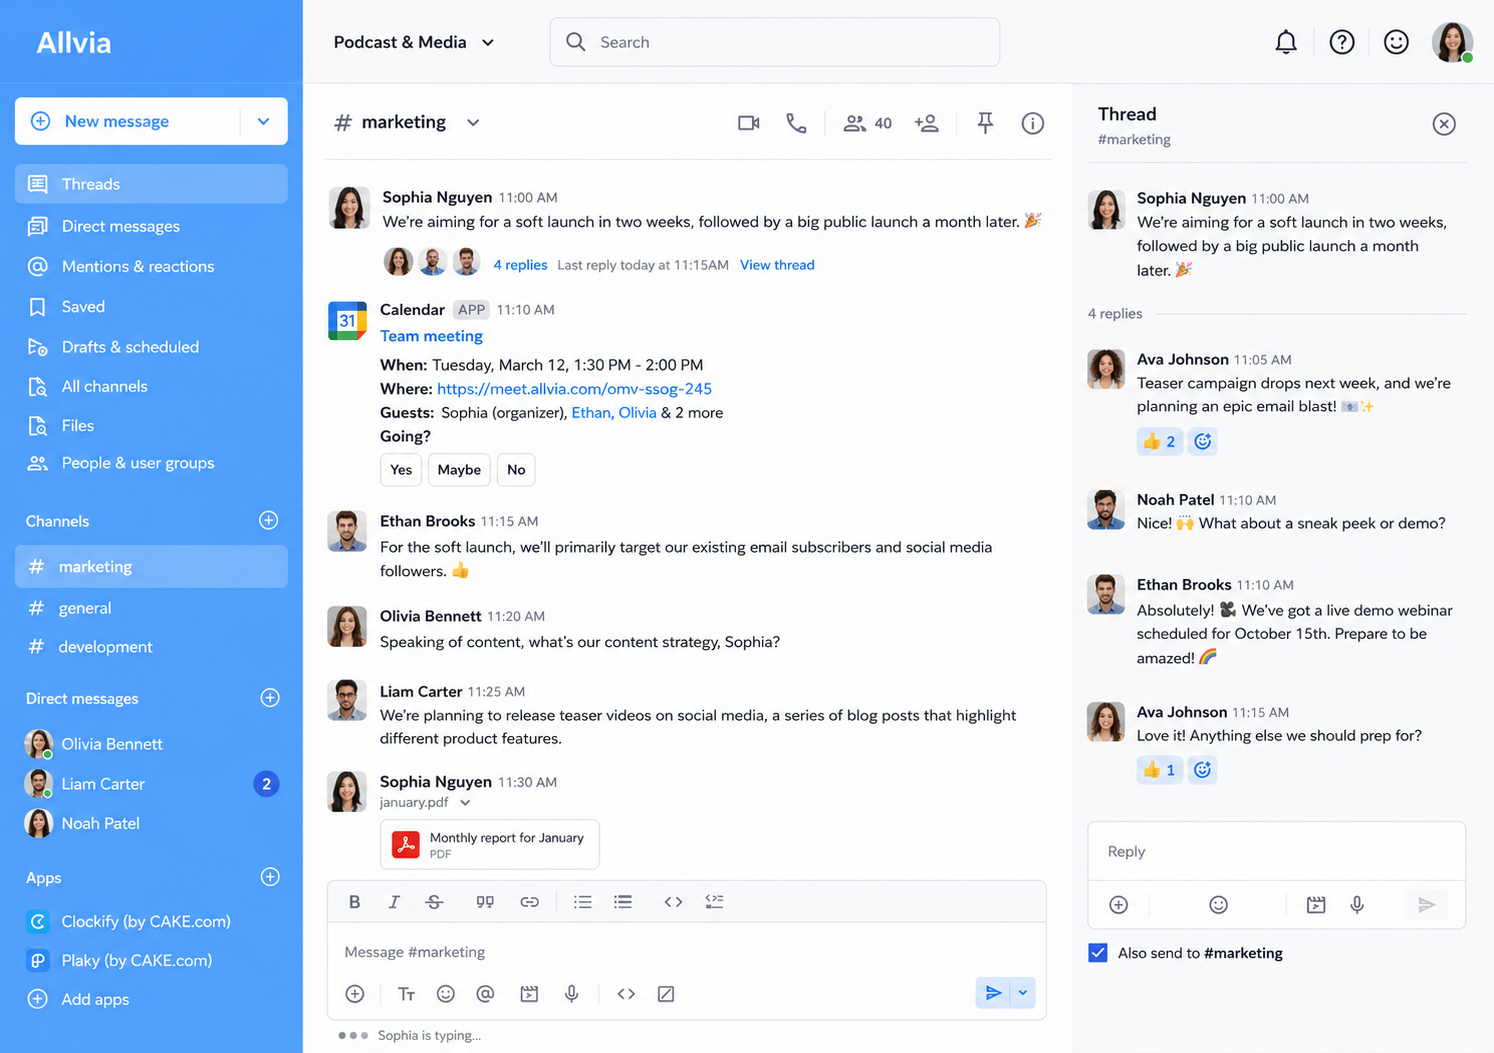
Product 02 — Allvia
Allvia.
Collaboration that thinks alongside the team.
Messaging, channels, knowledge, and AI productivity on a workspace that summarizes, retrieves, and acts. Plugs into your existing stack; replaces what no longer earns its place.
Messaging
Real-time · DM · threads
Channels
Department & topic workspaces
Knowledge
Searchable history · documents
AI tools
Summaries · insights · tasks
Researchers, engineers, and operators building the infrastructure behind frontier AI.
View all openingsCATEGORY
0 Roles
Don't see your role? We hire ahead of need.
Introduce yourselfPapers, technical reports, and methodology notes written by the same teams operating our production pipelines.
Open the full archive
Methodology
Multimodal
Agents